Zhisheng Zheng
Zhisheng Zheng
Home
News
Featured
Publications
Experience
CV
Light
Dark
Automatic
3
Reinforcement Learning for Music Generation with Pairwise Reward Modeling
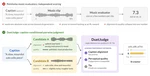
DuetJudge directly compares two music clips under the same caption, prioritizing text–music alignment before perceptual quality and reaching 71% agreement with human preferences. Its pairwise rewards improve Audex-2B, Audex-30B-A3B, and diffusion-based ETTA through reinforcement learning.
Zhisheng Zheng
,
Zhifeng Kong
,
Sang-Gil Lee
,
Jaehyeon Kim
,
Arushi Goel
,
David Harwath
,
Mohammad Shoeybi
,
Bryan Catanzaro
,
Wei Ping
Cite
Demo
Audio Samples
TransDubber: Learning Timeline-Preserving Speech-to-Speech Translation
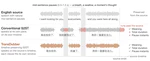
Speech-to-speech translation (S2ST) increasingly preserves what is said and how it sounds, but not necessarily when speech and silence …
Zhisheng Zheng
,
David Harwath
PDF
Code
Demo
Model
Testset
emotion2vec: Self-Supervised Pre-Training for Speech Emotion Representation
We propose emotion2vec, a universal speech emotion representation model. emotion2vec is pre-trained on open-source unlabeled emotion …
Ziyang Ma
,
Zhisheng Zheng
,
Jiaxin Ye
,
Jinchao Li
,
Zhifu Gao
,
Shiliang Zhang
,
Xie Chen
PDF
Cite
Code
Slides
Leveraging Speech PTM, Text LLM, and Emotional TTS for Speech Emotion Recognition
In this paper, we explored how to boost speech emotion recognition (SER) with the state-of-the-art speech pre-trained model (PTM), …
Ziyang Ma
,
Wen Wu
,
Zhisheng Zheng
,
Yiwei Guo
,
Qian Chen
,
Shiliang Zhang
,
Xie Chen
PDF
Cite
Slides
Cite
×