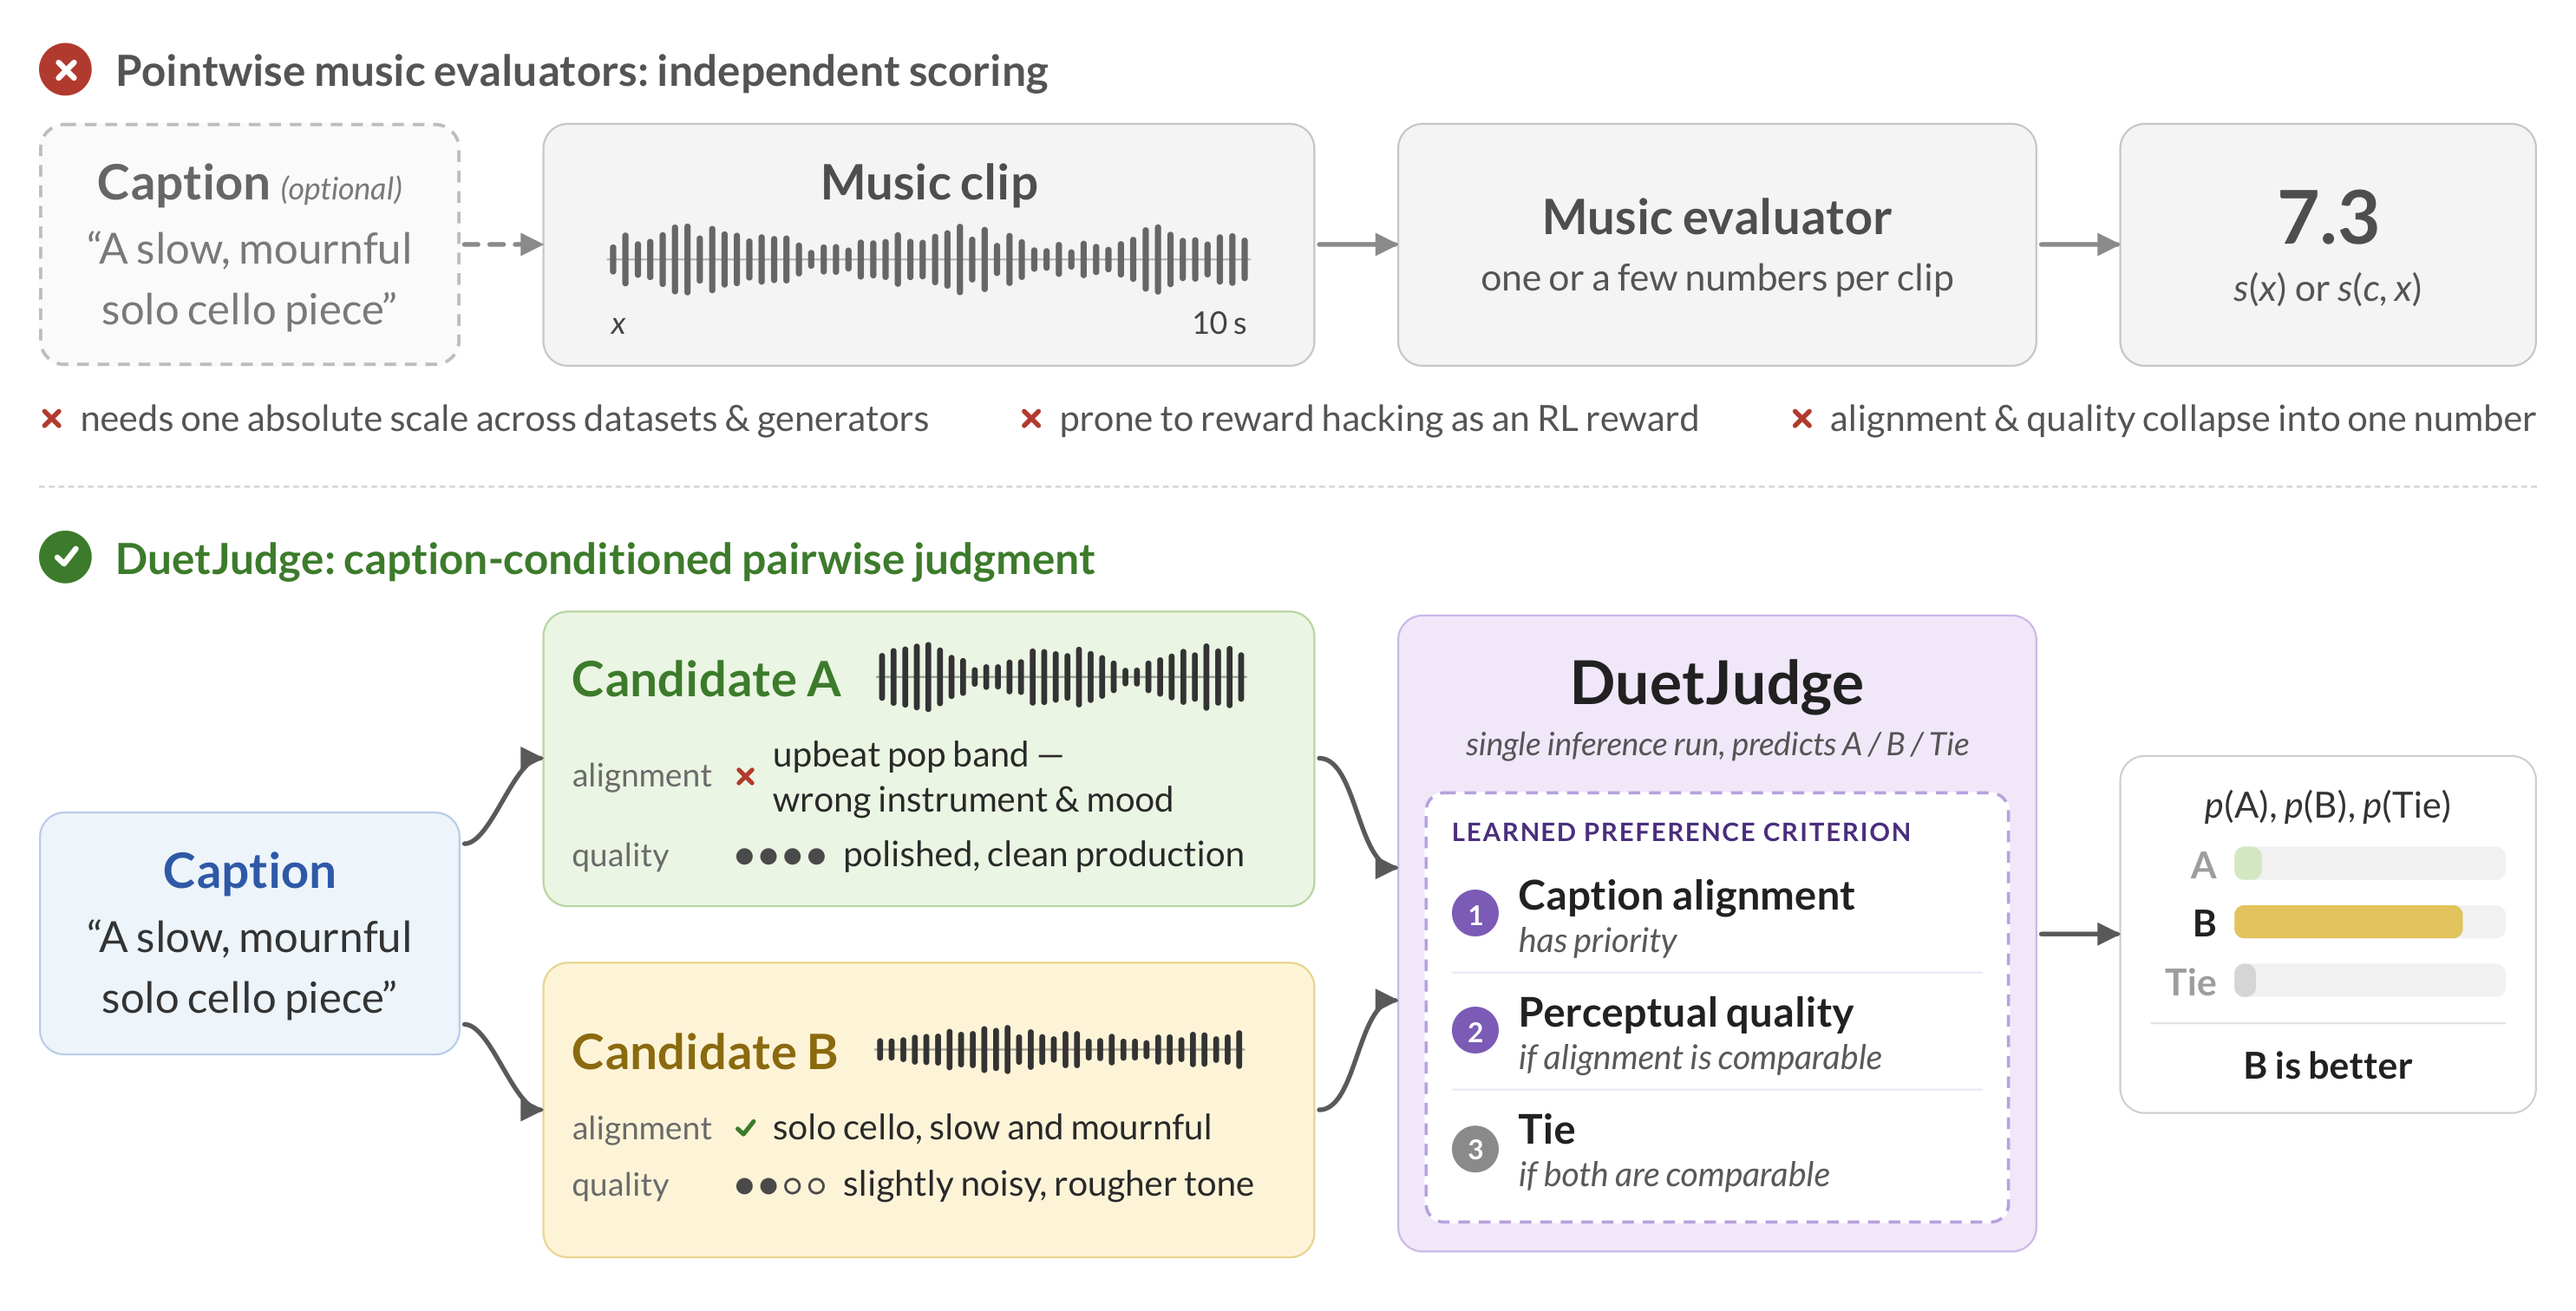
Improving text-to-music models through reinforcement learning (RL) requires a reward model that can clearly quantify the quality of a text–music pair. In this domain, this usually includes (i) how high-quality the outputs sound, and (ii) how well they align with the provided text. We introduce DuetJudge, an on-policy pairwise reward model that learns to directly compare two instrumental pieces conditioned on the same caption, without assigning independent scalar scores to each. DuetJudge is functionally a ternary classifier that outputs either one piece wins or they are a tie. Particularly, DuetJudge prioritizes text–music alignment, and then considers perceptual quality of the music. DuetJudge achieves 71% agreement with human preferences on our internal test set, outperforming all existing score-based baselines. To use DuetJudge as a reward model in text-to-music RL, we (i) design a reward score based on aggregated pairwise preference probabilities, and (ii) introduce classifier-free guidance (CFG)-aware policy optimization for text-to-music models trained with CFG. We test DuetJudge using multiple in-distribution and out-of-distribution text-to-music models, and find systematic improvements in both automatic metrics and human ratings. Ablation studies further favor direct pairwise rewards over a Bradley–Terry scalar baseline under the same training settings. These results confirm the effectiveness of our proposed DuetJudge, our data curation and augmentation methods, our reward model training recipes, and our text-to-music RL training recipes.